The character on the page
Narrator-plus-cast fails when everyone is Story. Keep Story on narration, Bright on the optimistic flatmate, Angry on the cold-footed flatmate. Strip “NARRATOR:” tags from spoken text. The download is spoken M4A only: no music bed, no lip-sync picture, no celebrity impersonation baked from a character sheet adjective list. Teams who search narrator and character voices AI usually arrive with a draft already written — A basement podcast in Chicago mixes a third-person narrator with two flatmates arguing over a broken heater. The feed needs three distinct mouths. That situation is exactly when Ryan Story, Aiden Bright, or Vivian Angry should be previewed on one sentence before a full paste, because the wrong family wastes the two-minute dubbing-credit minimum. Audio drama beginners and prose writers testing dual delivery also care about practical shipping: Speak in must match the language of the text, Conversation mode only when another speaker needs a different listed preset, and the download stays M4A speech without a music bed or lip-sync picture. If a proper noun slips, isolate it on its own line in the text editor and re-speak that beat instead of regenerating the entire scene. Keep original characters only; descriptions guide which catalogue voice
How a character voice stays distinct
Story frames the room; Bright jokes; Angry refuses another night without heat. No music bed from mydubly — add beds in your podcast editor if needed. Listen once without reading along so pacing problems show up before you spend a longer paste. While previewing narrator and character voices AI, compare Ryan Story, Aiden Bright, or Vivian Angry on the same opening sentence from your paste and listen without reading along. Proper nouns, times and UI labels fail first — put them on dedicated lines. One Speak in language per job keeps endings clean. Keep the same preset map the next time you open this scene so collaborators recognise the role by ear. Listen once on the device speakers your audience will use, then retake only the broken names. Write the stakes into concrete nouns before you spend another job of dubbing credits.
Example dialogue
Narrator: "The radiator clicked like a clock that had given up." A: "We can wear coats indoors." B: "I am done wearing coats indoors."
Who casts this voice
Real workflows for Narrator and Character Voices: table reads, pilot cold opens, session-zero audio and rehearsal pastes that match “A basement podcast in Chicago mixes a third-person narrator with two flatmates arguing over a broken”. Audio drama beginners and prose writers testing dual delivery pick Ryan Story, Aiden Bright, or Vivian Angry because a Clear habit undercuts this keyword. Styled-language Speak in covers zh/en/fr/de/it/ja/ko/pt/ru/es; other tongues need a permitted clone. Export stays speech-only M4A — no music bed, no lip-sync. Reuse the same casting notes next session so the role is recognisable by ear.
Build the scene
Paste narrator and dialogue, assign Story / Bright / Angry in Conversation mode, generate, fix any building name, download the M4A for the episode timeline. Confirm Speak in matches the language of the paste before you spend credits on a full take. Confirm Speak in, assign voices (Conversation mode when needed), generate once, then retake only broken lines. Download M4A for the folder that matches this narrator and character voices AI job — podcast timeline, LMS, cutscene bank or rehearsal speaker. Keep the same preset map the next time you open this scene so collaborators recognise the role by ear. Listen once on the device speakers your audience will use, then retake only the broken names. Write the stakes into concrete nouns before you spend another job of dubbing credits. Keep the same preset map the next time you open this scene so collaborators recognise the role by ear.
Casting mistakes to avoid
The narrator and character voices AI take fails when teams ignore the situation in the lede — A basement podcast in Chicago mixes a third-person narrator with two flatmates arguing over a broken heater. The feed needs three distinct mouths. — and paste into the wrong family. Bulletin pacing from News removes the swing Ryan Story, Aiden Bright, or Vivian Angry is for. GM notes left in the paste get spoken. Bracketed stage directions become audible words. Regenerating the same unbroken line against the two-minute dubbing minimum without rewriting wastes credits. Bilingual mashups in one job smear proper nouns that Audio needed clear.
After you listen
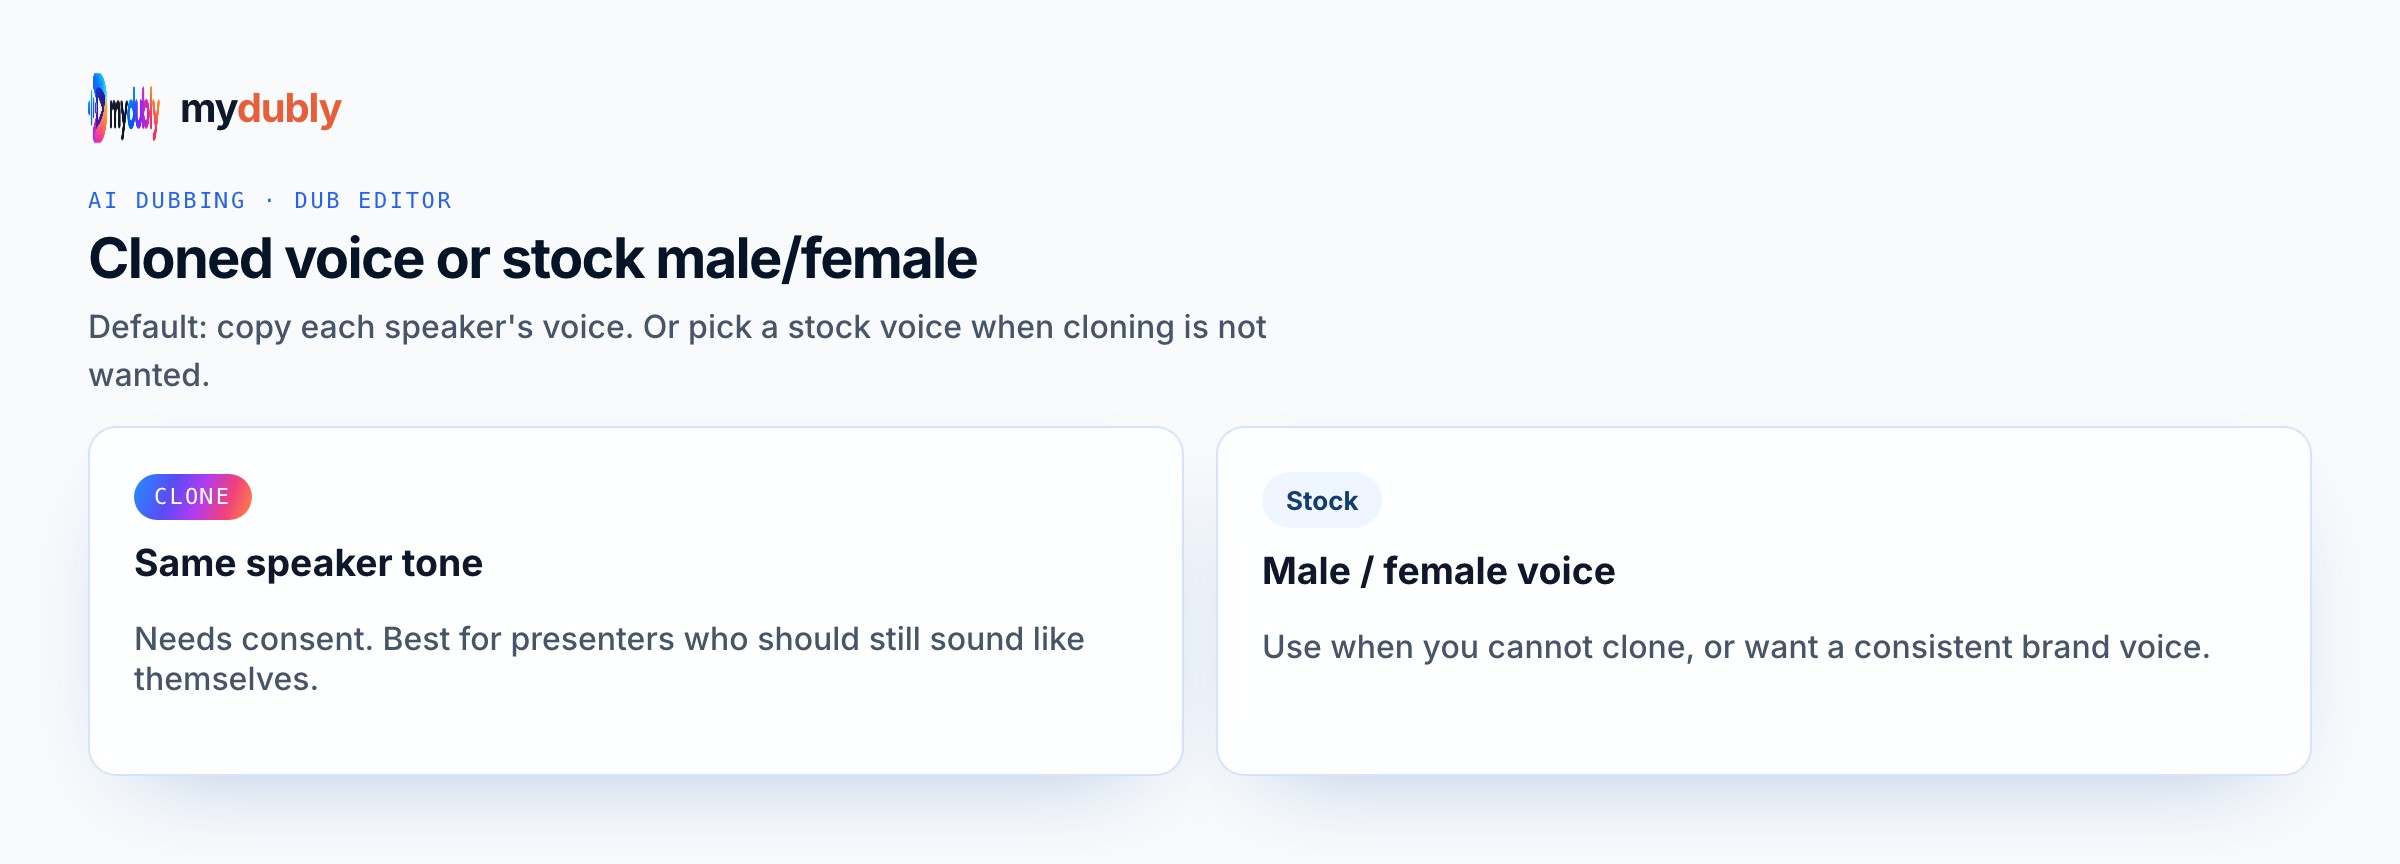
Keep narrator sentences shorter than the argument lines so the cast still owns the scene. If the take still feels wrong, change the wording or switch to another real preset — do not invent a hybrid Mood the catalogue does not list. After the first listen for narrator and character voices AI, rewrite soft or muddy clauses with shorter diction and keep Ryan Story, Aiden Bright, or Vivian Angry rather than stacking punctuation. A basement podcast in Chicago mixes a third-person narrator with two flatmates arguing over a broken heater. The feed needs three distinct mouths. is the ear test — if that situation still sounds wrong, you picked the wrong preset family or left stage directions in the paste. Batch useful runtime against the two-minute minimum, strip labels you do not want spoken, and document the voice map for the next episode. Clone remains permission-based; stock casting stays inside Studio and Mood catalogues.
Using the tool on this page
- Paste the text. The language it is written in is read from the words. Set the language it should be spoken in. The same language speaks the words as written.
- Studio and Mood voices play a short sample in Chinese, English, French, German, Italian, Japanese, Korean, Portuguese, Russian and Spanish. Hindi, Arabic, Turkish, Polish, Dutch, Swedish, Norwegian, Finnish and Hebrew need a recording of 3 to 15 seconds from someone you have permission to copy. A longer sample keeps the first 12 seconds.
- The reading is priced like a video dub: 120 credits per minute (12¢), minimum 2 minutes per file. A short paragraph still meets the 2-minute minimum.
- When it finishes, the reading stays on this page. Edit the script and speak it again: that is a new reading of the whole script at the same dubbing price, including the 2-minute minimum. Download the audio. Files stay 120 minutes. A video dub is a different job and opens in the dub editor. More is on the text to audio dubbing tool page.
Frequently asked questions
Can the narrator be Whisper or ASMR?
Yes if that fits the show — Whisper or ASMR presets are available — but Story is the usual narration choice. Pick what matches the episode.
Where do I open narrator and character voices?
On this page, or from the Text to Audio tab on the mydubly home page. The finished job opens in the text editor so you can change a line or a voice and speak the script again.
Can I clone a celebrity or copyrighted character?
No. Clone only a short sample you have permission to copy. Stock casting uses listed Studio and Mood voices for original characters.